These 16 data scientist resume examples run from intern to senior and cover Python, NLP, healthcare, marketing, education, consulting, full stack and energy work, plus a PhD researcher and a business analyst who moved into data science. Each sample has a note on what to copy. After them, you'll find what to write in the summary, which tools data science postings ask for most, how to write bullets that keep model results apart from business results, and how to build an entry-level resume.
Data Scientist Resume Examples
No full-time data science job yet? The intern, graduate student and entry-level samples are in the second half. Each candidate is fictional, with placeholder contact details, so use your own numbers.
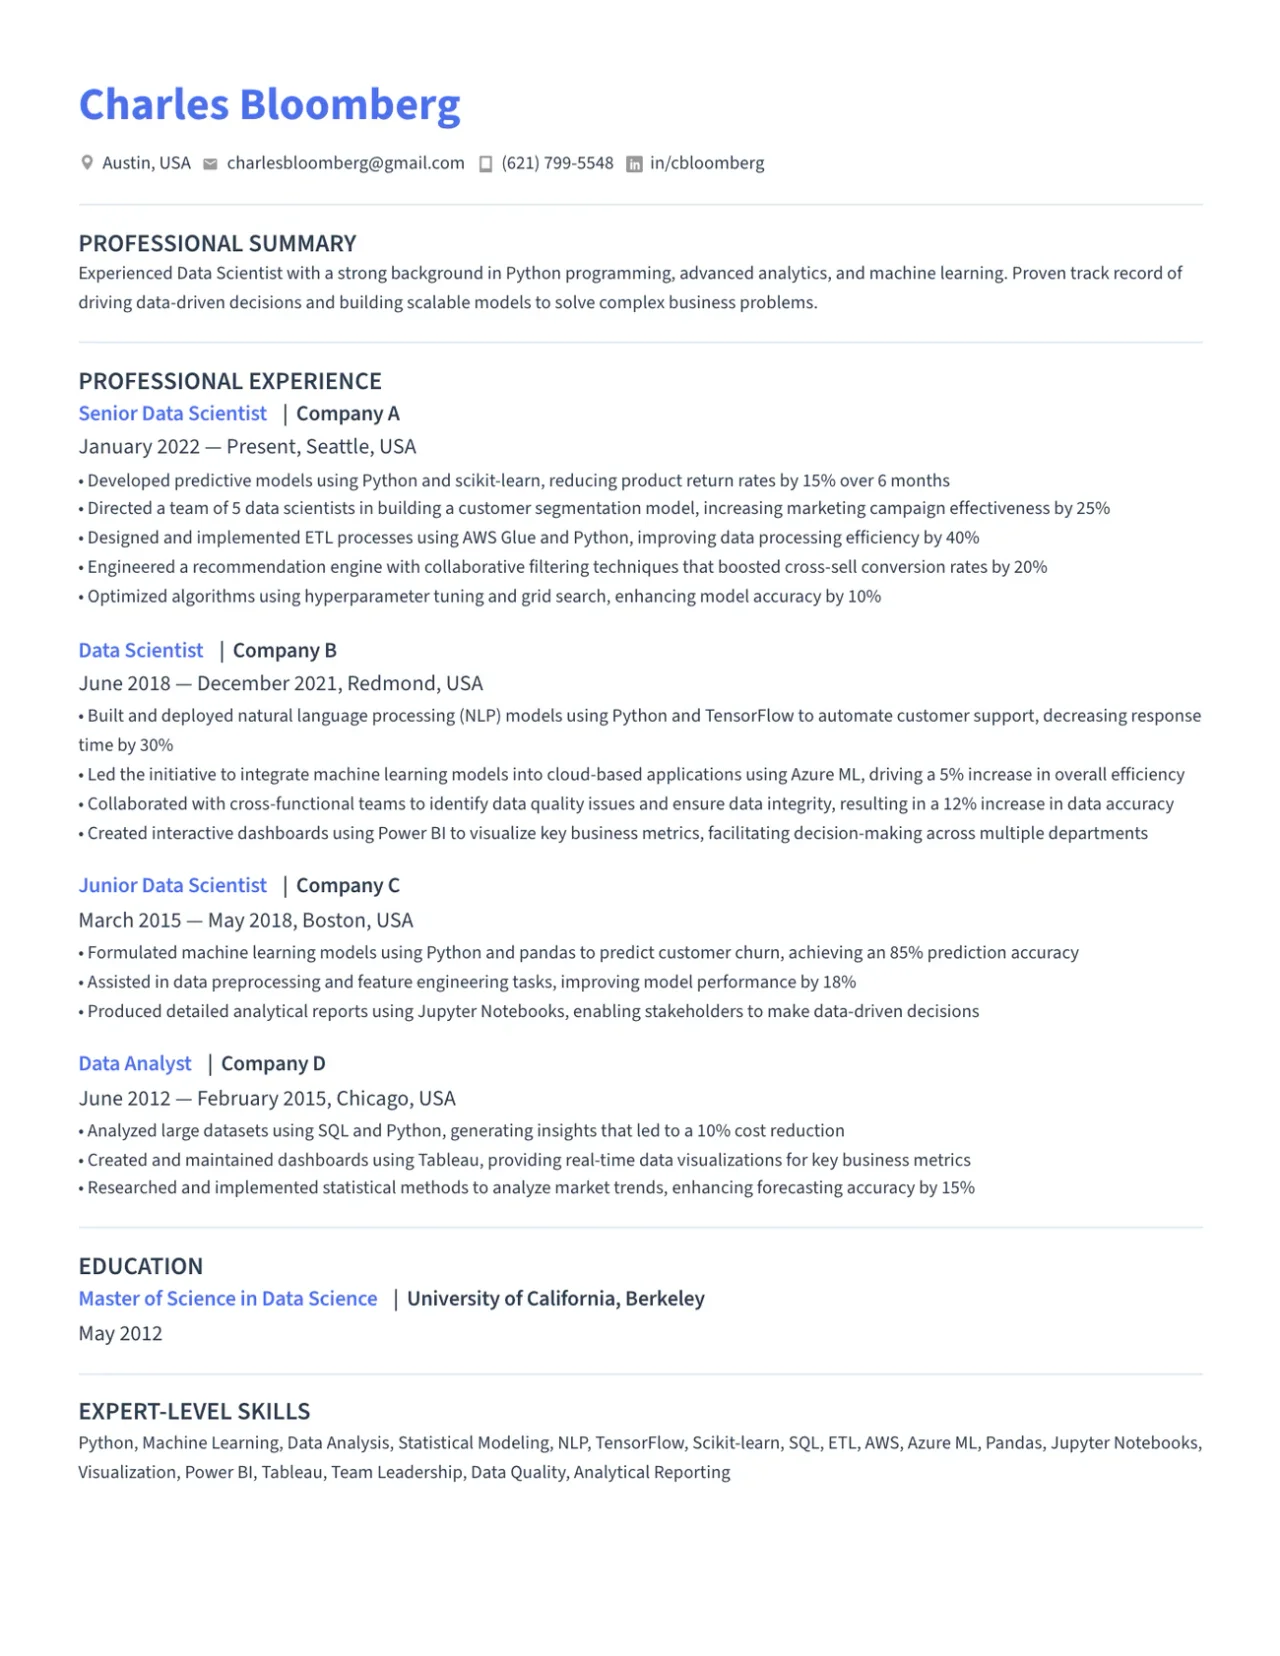
Senior Python data scientist resume (scikit-learn, AWS Glue, Azure ML)
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Experienced Data Scientist with a strong background in Python programming, advanced analytics, and machine learning. Proven track record of driving data-driven decisions and building scalable models to solve complex business problems.
PROFESSIONAL Experience
Senior Data Scientist | Company A
January 2022 — Present, Seattle, USA
• Developed predictive models using Python and scikit-learn, reducing product return rates by 15% over 6 months
• Directed a team of 5 data scientists in building a customer segmentation model, increasing marketing campaign effectiveness by 25%
• Designed and implemented ETL processes using AWS Glue and Python, improving data processing efficiency by 40%
• Engineered a recommendation engine with collaborative filtering techniques that boosted cross-sell conversion rates by 20%
• Optimized algorithms using hyperparameter tuning and grid search, enhancing model accuracy by 10%
Data Scientist | Company B
June 2018 — December 2021, Redmond, USA
• Built and deployed natural language processing (NLP) models using Python and TensorFlow to automate customer support, decreasing response time by 30%
• Led the initiative to integrate machine learning models into cloud-based applications using Azure ML, driving a 5% increase in overall efficiency
• Collaborated with cross-functional teams to identify data quality issues and ensure data integrity, resulting in a 12% increase in data accuracy
• Created interactive dashboards using Power BI to visualize key business metrics, facilitating decision-making across multiple departments
Junior Data Scientist | Company C
March 2015 — May 2018, Boston, USA
• Formulated machine learning models using Python and pandas to predict customer churn, achieving an 85% prediction accuracy
• Assisted in data preprocessing and feature engineering tasks, improving model performance by 18%
• Produced detailed analytical reports using Jupyter Notebooks, enabling stakeholders to make data-driven decisions
Data Analyst | Company D
June 2012 — February 2015, Chicago, USA
• Analyzed large datasets using SQL and Python, generating insights that led to a 10% cost reduction
• Created and maintained dashboards using Tableau, providing real-time data visualizations for key business metrics
• Researched and implemented statistical methods to analyze market trends, enhancing forecasting accuracy by 15%
Education
Master of Science in Data Science | University of California, Berkeley
May 2012
Expert-Level Skills
Python, Machine Learning, Data Analysis, Statistical Modeling, NLP, TensorFlow, Scikit-learn, SQL, ETL, AWS, Azure ML, Pandas, Jupyter Notebooks, Visualization, Power BI, Tableau, Team Leadership, Data Quality, Analytical Reporting
Most bullets name the tool next to the result it produced: scikit-learn for the return-rate model, AWS Glue for the ETL work, Azure ML for putting models into cloud applications. The return-rate bullet also gives a time window, 15% lower over six months. Tip: give the 85% churn accuracy in the Company C job its test set, such as a held-out quarter of customers.
Senior NLP data scientist resume (BERT, spaCy, PyTorch)
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Experienced Data Scientist specializing in Natural Language Processing with a track record of driving insights from vast datasets, implementing deep learning models, and leading successful NLP projects in diverse sectors.
PROFESSIONAL Experience
Senior Data Scientist, NLP | Company A
July 2020 — Present, Austin, USA
• Developed an NLP model that improved text classification accuracy by 25% using TensorFlow and Python, handling over 1 million texts daily.
• Spearheaded the deployment of an end-to-end machine learning pipeline, reducing processing time by 30% and increasing efficiency in data preprocessing and model training phases.
• Engineered complex natural language understanding algorithms to enhance Google Assistant's conversational capabilities, resulting in a 20% increase in user satisfaction scores.
• Led a team of 10 in the analysis of unstructured data sets and the extraction of actionable insights to inform product development, leveraging skills in Pandas, NLTK, and PyTorch.
• Collaborated with cross-functional teams to deploy NLP solutions in production, increasing response time efficiency by 15% and enhancing user experience across multiple platforms.
Data Scientist, NLP | Company B
June 2017 — June 2020, Seattle, USA
• Implemented language models for sentiment analysis, achieving an 18% improvement in customer sentiment understanding through the use of BERT and AWS SageMaker.
• Managed the automatic summarization project, using deep learning techniques to condense large texts by 50% while retaining critical information, enhancing internal reporting efficiency.
• Designed and deployed machine learning models that parsed and categorized customer reviews, reducing manual processing time by 40% and improving classification accuracy by 22%.
• Increased click-through rate by 12% through the optimization of Amazon’s recommendation system, applying collaborative filtering and content-based algorithms on extensive e-commerce data.
Junior Data Scientist | Company C
January 2015 — May 2017, Boston, USA
• Assisted in the development of NLP applications for client projects, utilizing libraries like SpaCy and Gensim to enhance text mining capabilities.
• Analyzed and cleaned large datasets, ensuring high data quality and integrity, leading to an 18% increase in model efficacy.
• Provided support in building predictive models that forecasted market trends, achieving an accuracy improvement of 15% through rigorous testing and validation processes.
Data Analyst Intern | Company D
June 2014 — December 2014, San Francisco, USA
• Contributed to the development of analytical models that processed and extracted insights from large datasets, improving data processing speed by 20%.
• Assisted in the creation of dashboards and visual reports using Tableau, enhancing data-driven decision-making capabilities for clients.
• Coordinated with senior analysts to perform comprehensive EDA, providing key insights that informed client strategies and decisions.
Education
Bachelor of Science in Computer Science | Massachusetts Institute of Technology
September 2010 — May 2014
Expert-Level Skills
Natural Language Processing, Machine Learning, Deep Learning, Text Mining, Data Analysis, Python, TensorFlow, PyTorch, NLTK, SpaCy, Gensim, AWS SageMaker, Pandas, Matplotlib, Seaborn, Jupyter Notebooks, SQL, Tableau, Data Visualization, Cross-Functional Collaboration, Project Management
Volume anchors the first bullet: a classification model handling more than 1 million texts a day. The libraries change from job to job, spaCy and Gensim in the junior role, BERT on AWS SageMaker in the middle one, NLTK and PyTorch now, so a reader can follow the work from text mining to BERT-based models.
Healthcare data scientist resume with readmission and risk models
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Experienced Data Scientist specializing in healthcare, skilled in applying statistical models and machine learning to improve patient outcomes and operational efficiency.
PROFESSIONAL Experience
Senior Data Scientist | Company A
January 2020 — Present, Rochester, USA
• Developed predictive models using Python and R to forecast patient readmission rates, reducing readmissions by 12% over one year.
• Led a team of 5 data analysts to analyze patient data, resulting in a 15% increase in data processing efficiency utilizing SQL and Apache Spark.
• Implemented machine learning algorithms to analyze imaging data, improving diagnostic accuracy by 18% using TensorFlow and Keras.
• Engineered an automated reporting system that reduced data reporting time by 40% using Tableau and Python.
• Designed a real-time data integration system, enhancing data accessibility and timeliness by 25% through the use of ETL processes and Apache Kafka.
Data Scientist | Company B
June 2017 — December 2019, Oakland, USA
• Created machine learning models that improved patient risk stratification, resulting in better-targeted interventions and a 20% reduction in adverse events.
• Spearheaded a project to clean and preprocess large healthcare datasets, reducing data inconsistencies by 30% using Python and PySpark.
• Collaborated with clinical teams to develop data visualization dashboards, enhancing data-driven decision-making and increasing user adoption by 50%.
• Improved the efficiency of data pipelines by 15% through the utilization of AWS cloud infrastructure and data warehousing services.
Junior Data Scientist | Company C
July 2015 — May 2017, San Diego, USA
• Analyzed patient data to identify trends and patterns, supporting the development of new healthcare policies and practices.
• Assisted in the deployment of natural language processing (NLP) models to categorize medical records, enhancing information retrieval speed by 20%.
• Conducted A/B testing to evaluate the effectiveness of different treatment plans, contributing to a 10% improvement in patient outcomes.
Data Analyst Intern | Company D
January 2014 — June 2015, Cleveland, USA
• Processed and analyzed large datasets using SQL and Excel, improving data accuracy and reporting capabilities.
• Provided insights and recommendations to healthcare providers based on data analysis, leading to a 5% increase in patient satisfaction.
• Researched and formulated data collection methodologies to enhance the quality of future data.
Education
Master of Science in Data Science | Harvard University
September 2012 — May 2014
Expert-Level Skills
Machine Learning, Predictive Modeling, Python, R, SQL, Apache Spark, TensorFlow, Keras, Data Visualization, Tableau, ETL, Apache Kafka, AWS, Data Preprocessing, Natural Language Processing, Statistical Analysis, Team Leadership, Problem-Solving, Communication
The first bullet pairs a model with a patient outcome and a period: readmissions down 12% over one year. Tools sit in the bullets that used them (Spark for the patient data, TensorFlow and Keras for imaging), so the skills list at the bottom is backed by the jobs above it. If your model informed a decision rather than changing an outcome, say what clinicians or administrators did with it.
Clinical NLP data science resume with research roles and a master's
Charles Bloomberg
New York City, New York, United States
charlesbloomberg@wisc.edu
Summary
Experienced Machine Learning researcher focusing on NLP and its impact in real-world applications. Interested in improving the company's current business operations and customer satisfaction by using Machine Learning, Deep Learning and Statistical Modeling.
Experience
NLP Research Intern | Company A
June 2021 - Present, New York, NY
• Responsible for clinical decision support system "AI-Pathway Companion" that helps physicians standardize and accelerate clinical decisions through AI.
• Developed natural language processing model that improved performance of current decision support system by 10%.
Data Science Researcher | Company B
June 2020 - June 2021, New York, NY
• Researched and performed a statistical, qualitative, and quantitative analysis in healthcare.
• Proposed approach for automatic generation of semi-structured representations of radiology reports that outperformed the baselines under quantitative evaluation and qualitative judgment by 5%.
• Worked on research problems in the medical field: reducing human time and effort devoted to annotating data, automatically detecting the presence of key findings from clinical reports, predicting patients' survival, simplifying lay-language of clinical reports.
• Teaching Assistant for courses: Python Programming, Data Science, and Math in Computing.
Data Science Intern | Company C
June 2019 - June 2020, New York, NY
• Designed and engineered machine learning systems to automate the sentiment polarity of drug reviews.
• Created data visualization graphics, translating complex data sets into comprehensive visual representations.
• Proposed approach outperformed baselines by 8% under quantitative metrics.
Software Engineer | Company D
June 2018 - June 2019, New York, NY
• Developed web-based applications for clients and assisted team members in enhancing client-side software solutions.
• Succeeded in delivering projects in half the time estimated by clients and increased project revenue by 50%.
Research Software Engineer Intern | Company E
June 2017 - June 2018, New York, NY
• Researched for a graduate thesis on distributed systems using the Azure Service Fabric platform.
• Designed and built mini microservice-oriented application for tracking and reducing electrical power failure.
Projects
Learning Semi-Structured Representations of Radiology Report | New York University
June 2020 - January 2021
• Proposed an approach for the automatic generation of semi-structured representations of radiology reports.
• Proposed approach outperformed the baselines under quantitative evaluation and qualitative judgment of a radiologist by 3%.
Education
Master of Science in Data Science | New York University
2021, New York, NY
GPA: 3.87
Skills
Industry Knowledge: Problem-Solving, Research, Business Communication, Teamwork, Collaboration, Critical Thinking, Passion, Presentation
Technical Skills: Python, Ruby, C#, Java, JavaScript, shell, PyTorch, Keras, TensorFlow, AWS, Apache Hadoop, Neo4j, Protégé, SQL, Git, Tableau, A/B Testing, Analytics, Statistics, Data Mining, Data Visualization, Machine Learning, NLP, Algorithm
Research-track resumes read best when the tasks are concrete, and this one names them: semi-structured representations of radiology reports, survival prediction, sentiment of drug reviews. The radiology work was judged two ways, by quantitative evaluation and by a radiologist, which tells a clinical team the output was checked by a domain expert. Tip: name the metric behind each gain over the baseline, such as F1 or ROUGE.
Marketing data scientist resume (segmentation, A/B tests, CLV)
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Data Scientist with extensive experience in marketing analytics, proficient in leveraging machine learning algorithms, statistical modeling, and data visualization tools to drive marketing strategies and optimize campaign performance.
PROFESSIONAL Experience
Senior Data Scientist | Company A
March 2019 — Present, Seattle, USA
• Developed predictive models using Python and R to enhance customer segmentation, resulting in a 15% increase in conversion rates over 12 months
• Engineered data pipelines utilizing SQL and AWS to process over 1TB of marketing data daily, improving data retrieval times by 40%
• Created interactive dashboards with Tableau, enabling real-time insights into campaign performance and leading to a 20% boost in marketing ROI
• Led a team of 5 data analysts in A/B testing initiatives, providing actionable insights that reduced customer acquisition cost by 10%
• Implemented machine learning algorithms to personalize marketing efforts, achieving a 25% improvement in email open rates and click-through rates
Data Scientist | Company B
January 2016 — February 2019, Mountain View, USA
• Spearheaded the development of data-driven marketing strategies, increasing user engagement metrics by 18% within 6 months
• Utilized Hadoop and Spark for large-scale data processing, enhancing the capability to analyze and interpret marketing data by 50%
• Conducted exploratory data analysis (EDA) to identify key trends and patterns in marketing campaigns, leading to a 22% reduction in churn rate
• Managed the integration of third-party data sources with internal databases, streamlining data flow and reducing processing time by 30%
Junior Data Scientist | Company C
June 2014 — December 2015, Dallas, USA
• Assisted in building customer lifetime value (CLV) models, which contributed to a 12% increase in customer retention over 9 months
• Provided in-depth analysis on marketing campaign efficiency using SQL and Excel, leading to cost savings of $50,000 annually
• Collaborated with cross-functional teams to validate data accuracy and ensure consistency across multiple projects, enhancing overall data integrity
Data Analyst Intern | Company D
May 2013 — May 2014, Boston, USA
• Conducted market research and data analysis for over 10 marketing campaigns, leading to a 10% increase in target market reach
• Supported the development and maintenance of databases, improving data retrieval efficiency by 15%
• Provided ongoing support to senior data scientists, contributing to data visualization projects in Tableau that facilitated better decision-making processes
Education
Master's Degree in Data Science | University of Washington
May 2013
Expert-Level Skills
Machine Learning, Predictive Analytics, Big Data Processing, SQL, Python, R, Tableau, AWS, Hadoop, Spark, Data Visualization, Marketing Analytics, A/B Testing, Statistical Modeling, Team Leadership, Analytical Thinking
Marketing hiring managers look for funnel metrics, and most bullets in the senior job supply one: conversion rate, marketing ROI, customer acquisition cost, email open and click-through rates. The customer lifetime value bullet in the junior job adds a window, nine months, which makes the retention figure easier to trust.
Full stack data scientist resume from pipelines to production
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Full-stack Data Scientist with over 8 years of experience in applying data-driven solutions to solve critical business challenges, utilizing advanced analytics and machine learning. Proven track record in developing end-to-end data pipelines, from data collection to production-level deployment.
PROFESSIONAL Experience
Senior Data Scientist | Company A
January 2020 — Present, Mountain View, USA
• Developed and deployed over 20 machine learning models into production, increasing predictive accuracy by 30% and reducing churn rates by 12% using Python, TensorFlow, and Scikit-Learn.
• Spearheaded data pipeline automation, reducing data processing time by 40% through the implementation of Apache Airflow and Apache Spark, thereby improving data accessibility.
• Led a team of 5 data scientists and engineers, managing project timelines, code reviews, and mentoring junior employees in data analysis and machine learning techniques.
• Optimized customer segmentation strategies using unsupervised learning algorithms, resulting in a 25% increase in targeted marketing campaign effectiveness.
• Collaborated with cross-functional teams to design and implement a real-time analytics dashboard using Tableau and SQL, delivering actionable business insights to stakeholders.
Data Scientist | Company B
June 2016 — December 2019, Menlo Park, USA
• Engineered advanced natural language processing (NLP) models to analyze user feedback, achieving 20% improvement in sentiment analysis accuracy utilizing NLP frameworks like SpaCy and NLTK.
• Created and managed ETL processes for handling petabyte-scale data using Hadoop and Apache Hive, reducing data retrieval times by 50%.
• Implemented A/B testing frameworks to optimize user interface changes, leading to a 15% increase in user engagement and a 10% boost in conversion rates.
• Drove the development of time-series forecasting models using ARIMA and LSTM, accurately predicting user behavior patterns and improving resource allocation by 18%.
Junior Data Scientist | Company C
August 2014 — May 2016, Austin, USA
• Analyzed customer data to segment markets and identify key trends, which resulted in a 20% increase in customer retention.
• Designed machine learning algorithms to enhance recommendation systems, improving user satisfaction scores by 15%.
• Assisted in the development of custom data visualization tools using D3.js, enabling better decision-making processes for stakeholders.
Data Analyst | Company D
January 2012 — July 2014, Seattle, USA
• Processed and cleaned large datasets using SQL and Python, ensuring data integrity for analysis and reporting.
• Built interactive dashboards and reports in Tableau, reducing reporting time for key metrics by 30%.
• Conducted statistical analysis to identify significant factors affecting customer behavior, aiding in the development of targeted marketing strategies.
Education
Bachelor of Science in Computer Science | Stanford University
2011
Expert-Level Skills
Machine Learning, Deep Learning, Data Analysis, Data Visualization, Python, R, SQL, Hadoop, Spark, NLP, TensorFlow, Keras, Scikit-Learn, Tableau, Apache Airflow, A/B Testing, Software Development, Team Leadership, Problem-Solving
The Airflow and Spark bullet, the Hadoop and Hive ETL bullet and the 20 production models together cover the whole chain the title promises, from data pipelines to deployment. The ARIMA and LSTM bullet adds time-series forecasting to the mix. Tip: split the first bullet so the accuracy gain and the churn result each get their own line.
Education data scientist resume (student retention, edtech)
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Experienced Data Scientist specializing in the education industry, with a proven track record of utilizing data-driven insights to improve student outcomes and optimize institutional processes.
PROFESSIONAL Experience
Senior Data Scientist | Company A
January 2020 — Present, San Francisco, USA
• Spearheaded the development of predictive analytics models to enhance student retention rates, resulting in a 15% improvement in course completion rates.
• Engineered machine learning algorithms to personalize learning experiences for over 45,000 online students using Python and TensorFlow.
• Collaborated with cross-functional teams to deploy data visualization dashboards, providing real-time insights on student performance metrics via Tableau.
• Optimized data collection processes, reducing data processing time by 30% using ETL pipelines built with Apache Airflow.
• Conducted A/B testing on new educational tools and features, analyzing results to identify significant improvements in user engagement.
Data Scientist | Company B
March 2018 — December 2019, Palo Alto, USA
• Developed robust machine learning models to predict and address student drop-out risks, increasing retention by 20%.
• Implemented natural language processing (NLP) techniques to analyze over 100,000 feedback comments, extracting actionable insights for product improvement.
• Managed vast educational datasets, applying data cleaning and preprocessing techniques to ensure data integrity and accuracy.
• Designed and conducted complex statistical analyses, leveraging R and SQL, to guide strategic decision-making.
Junior Data Scientist | Company C
June 2016 — February 2018, Austin, USA
• Developed and maintained data pipelines for educational analytics, ensuring seamless data flow and efficient processing.
• Assisted in building recommender systems to enhance content discovery for a user base of 20,000 students.
• Conducted exploratory data analysis (EDA) on large datasets, using Python libraries such as Pandas and NumPy.
Data Analyst Intern | Company D
June 2015 — May 2016, Boston, USA
• Conducted data analysis on student performance metrics, identifying trends and patterns to improve learning outcomes.
• Assisted in the development of analytical models to predict student success, utilizing regression analysis techniques.
• Generated weekly performance dashboards to track key metrics and support data-driven decision-making.
Education
Master of Science in Data Science | Stanford University
2015
Expert-Level Skills
Predictive Analytics, Machine Learning, Natural Language Processing (NLP), Data Visualization, A/B Testing, ETL Pipelines, Python, R, SQL, Tableau, Apache Airflow, TensorFlow, Pandas, NumPy, Power BI, Statistical Analysis, Data Cleaning, Team Collaboration, Technical Mentorship
In education the scale unit is students, and this sample counts them: 45,000 online students for the personalization work, 100,000 feedback comments for the NLP analysis, 20,000 students for the recommender. The retention bullets name the outcomes schools track, course completion and drop-out risk.
Data science consultant resume for retail and telecom clients
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Strategically-minded Data Scientist Consultant with extensive experience harnessing data analytics and machine learning to drive business insights and efficiencies. Proficient in leveraging statistical models and data visualization tools to inform and influence executive decision-making.
PROFESSIONAL Experience
Data Science Consultant | Company A
January 2021 — Present, San Diego, USA
• Developed predictive models using Python, resulting in a 15% increase in sales forecasting accuracy for retail clients.
• Managed end-to-end data projects, including data extraction, transformation, and loading (ETL) processes using SQL and Apache Spark, enhancing data pipeline efficiency by 30%.
• Created interactive data visualizations and dashboards in Tableau, aiding executive decision-making and reducing report generation time by 50%.
• Led a team of 5 data analysts in the implementation of machine learning algorithms, achieving a 20% improvement in churn prediction accuracy for a telecom client.
• Conducted comprehensive data audits, discovering and rectifying data quality issues, which improved client data integrity by 25%.
Senior Data Scientist | Company B
July 2016 — December 2020, San Francisco, USA
• Engineered machine learning models, including regression analysis and classification algorithms, to optimize marketing strategies, resulting in a 12% increase in campaign ROI.
• Spearheaded data mining initiatives using R and SQL, uncovering insights that led to a 10% cost reduction in supply chain operations.
• Collaborated with cross-functional teams to integrate AI solutions into business processes, reducing manual work by 40% and increasing process efficiency.
• Conducted A/B testing and statistical analysis on customer behavior data, providing actionable insights that enhanced user experience and increased customer retention by 15%.
Data Analyst | Company C
March 2014 — June 2016, Austin, USA
• Analyzed large datasets using advanced Excel functions, providing business insights that increased operational efficiency by 20%.
• Maintained and optimized data storage using SQL databases, ensuring data integrity and accessibility for ongoing analytical operations.
• Developed automated reporting systems using Python, reducing report generation time by 40% and increasing accuracy.
Data Science Intern | Company D
June 2013 — February 2014, Phoenix, USA
• Assisted in data collection and preprocessing for various machine learning projects, ensuring accuracy and completeness of data.
• Created data visualizations and reports in Matplotlib and Seaborn, aiding in the interpretation of analytical results.
• Conducted exploratory data analysis (EDA) to identify trends and patterns, providing foundational insights for further research.
Education
Bachelor of Science in Data Science | University of California, Berkeley
May 2013
Expert-Level Skills
Python, R, SQL, Apache Spark, Tableau, Machine Learning, Data Visualization, Statistical Analysis, ETL Processes, A/B Testing, Project Management, Data Mining, Cross-Functional Collaboration, Technical Reporting, Communication
Consulting resumes need the client type, and two bullets give it: retail clients for the sales forecasting model and a telecom client for churn prediction. The career runs intern, analyst, senior data scientist, consultant, which explains how this candidate came to lead a team of 5 analysts on client work.
PhD data scientist resume with machine learning research on power-grid data
Charles Bloomberg
New York City, New York, United States
charlesbloomberg@wisc.edu
Summary
Data Scientist / Machine Learning Engineer proficient in generative modeling, classification, prediction, and data processing. Capable of creating, developing, testing, and deploying machine learning models for numerous problem domains. Has demonstrated these abilities on several projects across several data science teams.
Experience
Machine Learning Research Lead | Company A
June 2021 - Present, New York, NY
• Led a research team solving major bulk US power grid problems using real, large-scale Synchrophasor data.
• Created a model to generate realistic synthetic anomaly data increasing data availability by at least 200% and a model to classify anomaly signatures achieving an F1 score of 97%.
• Created a system that automatically identified and categorized unprecedented anomaly labels with 96% accuracy.
• Created an online method to replace missing values during volatile anomalies while keeping errors 10%.
• Created two methods (for two use cases) to detect the start of an anomaly. Both methods achieve F1 scores of at least 95%.
Machine Learning Researcher | Company B
June 2020 - June 2021, New York, NY
• Created a model for topology classification and monitoring achieving 97% Accuracy from training on just 5% of the data.
• Developed a method to detect electricity fraud which increases detection rates by a factor of 20.
• Developed a model to predict the deaths of power equipment increasing the proportion of correct identifications by 700%.
• Performed detailed financial optimization of battery storage systems via their participation in Wholesale Power Markets.
• Performed battery storage degradation Modelling and optimization in power markets under degradation and managed a database of smart meter data on a Hadoop cluster.
Photonics Researcher | Company C
June 2019 - June 2020, New York, NY
• Performed simulations and optimizations to design multijunction solar cells, increasing efficiencies by 46%.
• Experimentally tested the power curves of 20 fabricated solar cells and performed wet-etching of multijunction solar cells in a cleanroom environment.
Education
Doctorate of Philosophy in Electrical Engineering | New York University
2019, New York, NY
GPA: 4.0
Bachelor of Science in Electrical Engineering | New York University
2015, New York, NY
GPA: 3.96
Skills
Languages: Python, SQL, Julia, MatLab, C++, C#
Tools: PyTorch, Tensorflow, Keras, Matplotlib, SkLearn, SciPy, Pandas, Jupyter Notebook, BigQuery, Google Cloud Platform, Hadoop, NumPy, Seaborn, Airflow, Docker, Kubernetes
Hard Skills: Information Theory, Statistics, Machine Learning Theory
Soft Skills: Technical Writing, Presentation Skills, Communication Skills, Leadership, Mentoring
This PhD in electrical engineering moved into machine learning, and the research bullets state their evaluation: an F1 score of 97% for classifying anomaly signatures, at least 95% for detecting the start of an anomaly, 96% accuracy on new anomaly labels. The first bullet names the data, real large-scale synchrophasor data from the US bulk power grid, which is what an energy or utility employer wants to see.
The rest of the samples go by career stage, from a data science intern to a senior data scientist with more than 10 years of experience.
Data science intern resume (Python, SQL, Tableau)
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Proactive and analytical Data Scientist Intern eager to apply data modeling and statistical analysis techniques to solve real-world problems. Strong foundation in machine learning, Python, and data visualization, complemented by collaborative teamwork skills.
PROFESSIONAL Experience
Data Science Intern | Company A
May 2023 — Present, Seattle, USA
• Designed and implemented machine learning models using Python and Scikit-learn, achieving a 15% increase in predictive accuracy for customer segmentation.
• Analyzed datasets exceeding 10 million rows using SQL and Python, enhancing data-driven decision making for marketing strategies.
• Developed interactive data visualizations with Tableau, presenting insights to senior management, which influenced a 10% budget reallocation.
• Collaborated with a team of 5 data scientists and engineers to optimize data pipelines, reducing data acquisition time by 20%.
• Conducted A/B testing for feature deployment, leading to a 10% improvement in user engagement on the platform.
Data Analysis Intern | Company B
June 2022 — August 2022, Redmond, USA
• Collected and preprocessed data from various sources using Pandas and SQL, improving data consistency by 25%.
• Built a dashboard using Power BI to monitor key performance indicators (KPIs), resulting in a 30% increase in operational efficiency.
• Conducted exploratory data analysis (EDA) to identify trends and patterns, which led to actionable insights for product improvement.
• Assisted in automating data quality checks using Python scripts, reducing manual efforts by 40%.
Research Assistant | Company C
September 2021 — May 2022, Chicago, USA
• Engineered datasets from various sources to support a study on consumer behavior involving over 50,000 unique data points.
• Applied statistical analysis using R to validate research hypotheses, contributing to a published paper in a peer-reviewed journal.
• Developed predictive models to analyze trends in consumer spending, boosting the project's outcome accuracy by 12%.
Junior Data Analyst | Company D
June 2020 — August 2020, Boise, USA
• Assisted in preparing data for analysis by cleaning and transforming raw data using Python, reducing data preparation time by 30%.
• Conducted market analysis to support business development strategies using statistical tools like SPSS.
• Provided ad-hoc data reports for the senior management team, enabling informed decision-making for business operations.
Education
Bachelor of Science in Data Science | University of California, Berkeley
May 2023
Expert-Level Skills
Machine Learning, Python, SQL, R, Tableau, Power BI, Data Preprocessing, A/B Testing, Statistical Analysis, Data Visualization, Team Collaboration, Problem-Solving, Communication
Four jobs, each with a tool: scikit-learn, Tableau, Power BI, R and SPSS. The Tableau bullet reports a result an intern can honestly claim, insights presented to senior management that influenced a 10% budget reallocation. The research assistant job adds a peer-reviewed paper, which is worth a line on any student resume.
Graduate student data scientist resume with two internships
Charles Bloomberg
New York City, New York, United States
charlesbloomberg@wisc.edu
Experience
Graduate Student Researcher | Company A
June 2021 - Present, New York, NY
• Developed an OpenCV computer vision pipeline for time series organoid microscopy images measuring growth and irregularity.
• Deployed via Kubernetes to distributed computing nodes connected to AWS S3. Visualizing results with Matplotlib and Plotly.
• Leveraged distributed deep learning with PyTorch for subtype classification of cortical cells from single-cell RNAseq data. Utilizing UMAP and density-based clustering (HDBSCAN) for visualization, dimensionality reduction, and cluster annotation.
• Researched new methods for outlier detection of stochastic time series and point cloud data.
• Wrote a paper on applications of functional depth (outlier detection and homogeneity testing) in biological experiments.
Student Researcher | Company B
June 2020 - June 2021, New York, NY
• Developed first Python library (seat depth) for statistical depth calculations, outlier detection, and homogeneity testing of time series and point cloud data.
• Analyzed RNA-seq data with non-parametric functional depth methods, running on a distributed computing cluster (CephFS).
Data Science Intern | Company C
June 2019 - June 2020, New York, NY
• Applied stacked models (XgBoost, regularized linear regression, and Facebook Prophet) to research which features most heavily impact depression and anxiety rates across the US.
• Implemented KNN clustering with PCA to analyze which states are most heavily affected by rates of depression, unemployment, and other factors caused by the economic crisis.
Data Science Intern | Company D
June 2018 - June 2019, New York, NY
• Created a deep learning model with Pandas, Tensorflow, and NLTK for text processing to classify startup sectors from funding data.
• Composed data engineering pipeline to generate and visualize funding metrics for clients.
Projects
Cruzhacks ; data visualization project
February 2021 - January 2022
• Won CruzHacks 2020 by creating a fully interactive website that brings clarity to the political process through interactive data visualizations. Built with Python (pandas), Plotly, and Dash, and hosted live on GCloud.
• A robust CNN to classify cell morphology from microscopy images.
• Built with PyTorch and trained on a multi-GPU cluster via Docker and Kubernetes.
Python Project : generate exploratory data plots
April 2020 - February 2021
• Python package to instantly generate common exploratory data plots without cleaning your DataFrame.
• Built with Python (pandas, NumPy, plotly), Published on PyPI.
• A lightweight Python package for quick analysis of small subsets of large, numeric data. Inspired by the pandas API and designed for data too large to fit in local memory.
Education
Applied Mathematics, M.S. | University of California, Santa Cruz
2022, Santa Cruz, California
GPA: 3.5
Computational Mathematics, B.A. | University of California, Santa Cruz
2021, Santa Cruz, California
GPA: 3.5
Skills
Programming: Python (Scikit-learn, Pandas, Numpy, PyTorch, Plotly, Matplotlib, Scipy, XgBoost), SQL, Swift, C, Java, Fortran
Software: Docker, Kubernetes, Slurm, Jupyter, AWS S3, Ceph, Git, Bash, Google Cloud, Anaconda
Graduate researchers can copy how this sample turns lab work into data science work: an OpenCV pipeline deployed with Kubernetes on data in AWS S3, and PyTorch classification of cell subtypes from single-cell RNA-seq data. The projects carry the rest, including a Python package published on PyPI. Tip: give each internship one finding, such as which features the stacked model ranked highest.
Entry-level data scientist resume from a data analyst job
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Aspiring Data Scientist with strong analytical skills and experience in data manipulation, statistical analysis, and machine learning. Proven ability to deliver insights and data-driven solutions.
PROFESSIONAL Experience
Data Analyst | Company A
January 2023 — Present, Mountain View, USA
• Analyzed and visualized large datasets using Python, resulting in a 15% improvement in marketing campaign targeting.
• Developed and maintained dashboards in Tableau, ensuring that stakeholders have up-to-date metrics and key performance indicators.
• Conducted A/B testing on new advertising strategies, leading to a 10% increase in click-through rates.
• Collaborated with cross-functional teams to identify data requirements, optimizing data collection processes by 20%.
• Utilized SQL to query databases, improving data retrieval time by 25% through optimized query structures.
Data Science Intern | Company B
June 2022 — December 2022, Armonk, USA
• Assisted in the development of machine learning models for predictive analytics, increasing accuracy by 12% using Python and Scikit-learn.
• Cleaned and preprocessed large datasets, reducing null values and outliers by 30% for more accurate modeling.
• Conducted exploratory data analysis (EDA) using Pandas and Matplotlib, uncovering key insights for business strategies.
• Implemented linear regression models to forecast sales data, contributing to the development of strategic initiatives.
Data Analyst Intern | Company C
January 2022 — May 2022, Dallas, USA
• Analyzed customer data using R, identifying trends that led to a 5% increase in customer retention rates.
• Created interactive data visualizations with Power BI, providing actionable insights to marketing and sales teams.
• Conducted statistical analyses to support market research initiatives, enhancing data-driven decision-making processes.
Research Assistant | Company D
September 2021 — December 2021, Houston, USA
• Conducted data collection and analysis for academic research, resulting in a published paper on data-driven strategies.
• Utilized SQL to manage and query research databases, improving data accessibility by 30%.
• Developed dashboards and data visualizations using Google Data Studio to present research findings clearly.
Education
Bachelor of Science in Data Science | University of Texas at Austin
September 2018 — May 2022
Expert-Level Skills
Python, R, SQL, Tableau, Power BI, Scikit-learn, Data Visualization, Statistical Analysis, Machine Learning, Data Preprocessing, A/B Testing, Team Collaboration, Problem Solving, Time Management
This candidate holds a data analyst title and targets data science, so the summary says "Aspiring Data Scientist" and the internship lists the modeling work: scikit-learn models, linear regression sales forecasts, EDA in pandas and Matplotlib. The A/B testing bullet in the current job gives a clean result, a 10% rise in click-through rate.
Junior data scientist resume with research and internship work
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Ambitious Junior Data Scientist with expertise in statistical analysis, machine learning, and data visualization. Proven ability to conduct thorough data analytics and contribute to impactful decision-making processes.
PROFESSIONAL Experience
Junior Data Scientist | Company A
January 2023 — Present, Seattle, USA
• Developed predictive models utilizing Python and R, improving forecasting accuracy by 20% and driving informed business decisions.
• Implemented machine learning algorithms on datasets containing over 1 million records, reducing processing time by 30% through optimized code.
• Created interactive data visualizations using Tableau, enhancing team’s ability to interpret complex data leading to a 15% increase in analytical insights.
• Collaborated with cross-functional teams to analyze user behavior data, leading to a 10% increase in user retention.
• Conducted A/B testing for new product features, facilitating data-driven decision-making and reducing time-to-market by 25%.
Data Analyst Intern | Company B
June 2022 — December 2022, Seattle, USA
• Processed and analyzed datasets comprising over 500,000 rows using SQL, contributing to the optimization of supply chain operations.
• Designed and maintained dashboards in Power BI, providing key performance indicators that improved departmental efficiency by 12%.
• Assisted in developing regression models to forecast sales trends, achieving a 10% reduction in overstock situations.
• Participated in weekly data review meetings, presenting insights that led to a 5% cost savings in logistics operations.
Research Assistant | Company C
September 2020 — May 2022, Boston, USA
• Engineered data collection pipelines using Python and AWS, resulting in more efficient data gathering for research projects by 40%.
• Conducted exploratory data analysis (EDA) on various datasets to uncover trends and patterns, aiding in publication of 3 research papers.
• Collaborated with senior researchers to develop machine learning models, improving prediction accuracy for study outcomes by 15%.
Data Science Intern | Company D
June 2019 — August 2020, San Francisco, USA
• Analyzed social media datasets using Python to identify key trends and insights, increasing client engagement strategies by 18%.
• Created detailed data visualizations in matplotlib and Seaborn, making complex data more accessible to non-technical stakeholders.
• Optimized SQL queries for large datasets, reducing data retrieval times by 25% and increasing report generation efficiency.
Education
Bachelor of Science in Data Science | University of Washington
June 2022
Expert-Level Skills
Python, R, SQL, Machine Learning, Data Analysis, Data Visualization, Tableau, Power BI, AWS, Data Mining, Statistical Analysis, Problem Solving, Critical Thinking, Communication
More than three years of research and internships come before the junior title, and the research job ties exploratory analysis to an outcome a reader can verify: three published papers. Tip: say what the 20% forecasting improvement in the current job was measured against, such as the error of the forecast it replaced.
Data scientist resume after a business analyst role
Charles Bloomberg
New York City, New York, United States
charlesbloomberg@wisc.edu
Summary
Data scientist with 3 years of experience in Php, Javascript, SQL, and C++. Highly skilled in application development, data analytics, and management of technical projects. Proven ability to generate high-quality analytical reports and source data from various data sources to create accurate, reliable reporting and analysis.
Experience
Senior Data Scientist | Company A
June 2021 - Present, New York, NY
• Performed K Means clustering on the rides to identify the high performing, low performing, and medium performing rides.
• Identified cold spots within the park using clustering which helped develop a plan to tackle the cold spots of the park.
• Predicted operation cases for 2020 which helped the operations department identify days on which it's more likely to receive a lot of cases to allocate resources accordingly.
• Performed customer segmentation using K Modes as all fields were categorical.
• Created a binary classification model to predict if an operations case will breach SLA with an f1 score of 89 percent and created a web application around this using streamlit.
Business Analyst | Company B
June 2020 - June 2021, New York, NY
• Analyzed the trend in revenue, occupancy, and ARR by creating dashboards.
• Wrote queries using SQL to extract data and analyze it, predicting future revenue using Excel and Alteryx.
• Automated reports using Google Sheets and Script Editor, and increased revenue by 3.6 million in 5 months by identifying the high booking period.
Data Analyst Intern | Company C
June 2019 - June 2020, New York, NY
• Developed several MIS reports for various departments including finance, IT, HR, etc which helped to improve decision making and internal business process and wrote queries on Microsoft SQL to pull relevant data.
Projects
Project A
August 2020 - May 2021
• Built a model using CatBoost Classifier for binary classification and created a web application that can be used to classify if a user can be granted a loan or not using pycaret, streamlit, and docker.
Project B
August 2019 - June 2020
• Created a binary classification model using logistic regression to classify the issues as an alert or not and predict the probability of an alert case.
• Automated WhatsApp messages using Twilio so when the model predicts an alert case, the safety executive is notified.
• Deployed the model on a web app using Flask and Heroku.
Education
Bachelor of Engineering in Computer Science | University A
2019, Toronto, Ontario
GPA: 3.69
Skills
Languages: Java, Python, SQL (MS SQL Server), PySpark
Framework : Flask, Streamlit, Selenium
Developer Tools : Git, Docker, PyCharm, IntelliJ, Heroku, Jupyter
Libraries: Pandas, NumPy, Plotly, Keras, OpenCV, Scikit-learn, PyCaret
The path runs data analyst intern, business analyst, data scientist, and the bullets change with it: SQL reports and dashboards first, then K-means clustering, K-modes segmentation and an SLA-breach classifier with an F1 score of 89%. The two projects add deployment work employers ask about, a CatBoost model behind a Streamlit app in Docker and a Flask app on Heroku.
Mid-level data scientist resume with models in production
Charles Bloomberg
New York City, New York, United States
charlesbloomberg@wisc.edu
Summary
Experienced Data Scientist, passionate about leveraging Data to answer scientific and Business questions
Experience
Data Scientist | Company A
June 2020 - Present, New York, NY
• Analyzed the company's sales data to identify the unmonetized Deal Registration transaction and determine the total value of uncaptured opportunities.
• Built a Real-time opportunity evaluation engine to identify the best deals to be applied by a seller for every order to maximize the margins of the transaction. The outcome of the project is estimated to generate additional revenue of 100 Million dollars over 3 years.
• Developed and deployed multiple propensity models by using machine learning methodologies including Random forest, XGBoost and SVM, to determine the propensity of a customer to buy a product category in the next 3 months, and applied the models to the existing customer base to generate leads for sellers and help the marketing team create personalized marketing campaigns.
• Built and deployed an NLP based model by fine-tuning BERT to determine the customers intent for tracking their shipment from customers to email, and provide an immediate and automated response of the current status of the customers' shipment with an SLA of less than 80 secs with a precision of 98%.
• Developed and deployed an information extraction tool to extract information from PDFs by using OCR to extract text and their relative positions from the PDF and build a transformer-based sequence model to extract the information with 92% accuracy.
Data Science intern | Company B
June 2019 - June 2020, New York, NY
• Developed a Variational Autoencoder model, to create a reduced dimensional encoding of each cell in a single cell RNASeq data of the drug product generated by the different manufacturing process.
• Performed unsupervised clustering of the reduced dimension encoding to understand the percentage of T cells in the drug products generated by the different manufacturing process and performed statistical tests to answer why one process is better than the other. This process of dimensionality reduction+ unsupervised clustering led to higher heterogeneous clusters as compared to traditional PCA-based methods.
• Developed a logistic regression model to determine the patient outcome from the reduced dimensional encoding of single-cell RNA seq data.
Lead Assistant Manager Data Sciences | Company D
June 2017 - June 2018, New York, NY
• Led the development of an AI-powered Content Extraction product by leveraging deep learning methodologies for a leading logistic company, to extract information from the invoices in a structured format with 87% accuracy. This product reduced the SLA for processing an invoice from 3 Mins an invoice to 20 secs.
• Developed and deployed an anomaly detection engine for a leading media client, to flag customer misuse of subscription. This solution leveraged real-time clickstream data by applying LSTM-based deep learning models and generated an estimated $8.75 Million /year in savings to the client.
Education
Master of Science in Biology- Data Science focus/Bioinformatics | New York University
2020, New York, USA
Bachelor of Science in Computer Science | New York University
2018, New York, NY
Certifications
Deep Learning Specialization | Coursera
2021
Natural Language Specialization | Coursera
2021
Skills
Machine Learning: Python (scikit-learn, pandas, NumPy), keras, TensorFlow, Pytorch, Spark MLlib
Data Processing: SQL, Apache Spark, Hadoop, Hive, Pig
Data Visualization Tools: Tableau, RStudio, Power BI, LaTeX, Advanced Excel
Cloud Platforms/Environments: AWS, MS Azure, Heroku, GitHub
Database: MySQL, MongoDB
The current job covers three kinds of model with a measure for each: propensity models (Random Forest, XGBoost, SVM) applied to the customer base to generate leads, a fine-tuned BERT model answering shipment emails at 98% precision, and an OCR extraction tool at 92% accuracy. The internship adds a less common specialty, a variational autoencoder on single-cell RNA-seq data, which suits biotech postings.
Senior data scientist resume (10+ years, team lead, Google Cloud)
Charles Bloomberg
charlesbloomberg@gmail.com
PROFESSIONAL SUMMARY
Experienced Data Scientist with over 10 years of experience in designing and deploying machine learning models, optimizing data-driven processes, and providing actionable insights. Proven track record of improving operational efficiency and solving complex problems using advanced analytical techniques.
PROFESSIONAL Experience
Senior Data Scientist | Company A
January 2020 — Present, Mountain View, USA
• Developed and deployed over 50 machine learning models, resulting in a 20% increase in predictive accuracy and leading to data-driven decision-making
• Spearheaded the migration to a cloud-based data infrastructure, improving data processing speed by 30% using Google Cloud Platform tools like BigQuery and Cloud Dataflow
• Collaborated with cross-functional teams to analyze user data from over 1 billion users, generating actionable insights that drove a 15% increase in user engagement
• Conducted A/B testing to optimize new product features, leading to a 12% increase in user retention across multiple platforms
• Engineered automated data pipelines using Python, SQL, and Apache Airflow, reducing data processing time by 50%
Data Scientist | Company B
August 2015 — December 2019, Menlo Park, USA
• Built predictive models using machine learning algorithms like Random Forests, XGBoost, and Neural Networks to forecast user behavior, achieving a 25% improvement in accuracy
• Managed large datasets comprising terabytes of data, utilizing Hadoop, Spark, and HDFS for efficient storage and processing
• Designed and implemented data visualization dashboards with Tableau and Power BI, which were adopted by over 200 stakeholders
• Led a team of 5 junior data scientists, providing mentorship and guiding project development to meet deadlines and quality standards
Data Analyst | Company C
June 2012 — July 2015, Austin, USA
• Analyzed and interpreted complex data sets to identify trends and patterns, providing actionable insights that led to a 10% increase in operational efficiency
• Created and maintained SQL databases to handle large volumes of data, ensuring data accuracy and availability
• Prepared detailed analytical reports and presented findings to executive management, influencing strategic decisions
Junior Data Analyst | Company D
January 2010 — May 2012, Seattle, USA
• Assisted in the development of data collection systems and data analysis strategies, improving the accuracy and efficiency of data operations
• Conducted data cleaning and preprocessing for large datasets, reducing errors by 15% and ensuring high data quality
• Created visualizations and reports to communicate complex data insights to non-technical stakeholders
Education
Master of Science in Data Science | Stanford University
June 2009
Expert-Level Skills
Machine Learning, Data Analysis, Python, R, SQL, Big Data Technologies, Cloud Computing (Google Cloud Platform, AWS), Data Visualization (Tableau, Power BI), Statistical Analysis, Data Mining, Data Governance, Project Management, Team Leadership, Problem Solving, Communication
Senior scope shows in numbers a reader can place: more than 50 models deployed, user data from over 1 billion users, dashboards adopted by more than 200 stakeholders and a team of 5 junior data scientists. The migration bullet names the Google Cloud tools, BigQuery and Cloud Dataflow, instead of saying "cloud" alone.
What should a data scientist resume summary say?
In two or three sentences, give your title and years, the kind of models or analysis you build, one result with its measure, and the role you want next. The summary previews your best bullet. It shouldn't introduce a claim that appears nowhere else on the page.
A pattern you can fill in: "Data scientist with [N] years building [churn, forecasting or ranking] models in Python and SQL for [industry]. Built [model] that [moved which metric from A to B on a held-out test set, or which team now uses it]. Looking for a [senior or ML-focused] data scientist role working on [problem area]."
With no data science job yet, write an objective around your best project: "Recent [degree] graduate in [field] with [internship or research] experience in Python, SQL and [scikit-learn or PyTorch]. [One project and how you evaluated it.] Seeking an entry-level data scientist role on [type of problem]." Skip stock adjectives. The method and the result carry the information. For more patterns, see these resume summary examples.
If you want a first draft, the summary generator runs in the Rezi app with a free account. Check that every claim in the draft matches a bullet on your resume.
Which skills and tools should a data scientist resume list?
List the languages, libraries, platforms and methods you have actually used, grouped so a reader can scan them, with the ones the posting names first. Python and SQL lead. In 2025 US job postings for data scientists, Python appeared in 66% and SQL in 51%, followed by R (34%), Tableau (22%), Microsoft Power BI (19%), AWS (17%) and Microsoft Azure (13%), according to O*NET's hot technologies list for data scientists (Lightcast posting data; O*NET is published by the U.S. Department of Labor under CC BY 4.0).
A grouped skills section, built from the samples above and the O*NET list:
- Languages: Python, SQL, R, plus Scala or Java when the posting asks for them
- Machine learning: scikit-learn, XGBoost, TensorFlow, PyTorch, Keras
- Data processing: pandas, NumPy, Apache Spark, Hadoop and Hive, Snowflake, BigQuery, Apache Airflow
- Cloud and deployment: AWS SageMaker, Azure Machine Learning, Docker, Kubernetes, Flask or Streamlit apps
- Methods: regression, classification, clustering, time-series forecasting, A/B testing, NLP
- Visualization: Tableau, Power BI, Matplotlib, Seaborn, Plotly
The mid-level sample groups its skills the same way, which is easier to scan than one long line. Every tool you list should also appear in a bullet, so a reader can see what you did with it. Communication and teamwork belong in bullets too: "presented insights to senior management" says more than a soft-skills list.
Certifications are supporting evidence. A cloud machine learning certification helps most when the posting names that platform: AWS has an associate-level Machine Learning Engineer certification, and Google Cloud has the Professional Machine Learning Engineer, which Google recommends for people with 3+ years of industry experience. Microsoft has retired the Azure Data Scientist Associate certification, along with its renewal assessment, so don't plan your study around it. Course certificates, such as Coursera's Deep Learning Specialization, carry more weight next to a project that used what the course taught. To see which tools from a posting your resume doesn't mention yet, the keyword scanner runs in the Rezi app with a free account.
How do you write data scientist resume bullets?
Say what problem you worked on, the data and method, how you evaluated the result, and what changed because the model or analysis existed. Those are separate claims, and each one deserves its own clause or bullet so a reader can check it. O*NET's task list for data scientists names these steps separately: testing and validating models, comparing them with performance metrics, and presenting results to management or other users.
- Analysis: the question, the data and the statistical method.
- Model development: the metric, the baseline it beat and how you validated it.
- Deployment: where the model runs, who uses its output, and how you monitor it.
- Business effect: what changed after launch, and how you know the model caused it.
Pick the metric that fits the task: precision and recall or AUC for classification, mean absolute error or MAPE for forecasting, NDCG for ranking. Accuracy alone can mislead on rare events. If fraud shows up in 1% of transactions, a model that flags nothing is 99% accurate and catches no fraud. Whether you write the bullet by hand or draft it in an AI resume builder like Rezi, put the metric name next to the number so a reviewer knows what your 92% measures.
Here is a typical first-draft bullet and two stronger versions:
- Before: "Built machine learning models to predict customer churn."
- Better, with the same facts: "Built an XGBoost churn model in Python on subscriber billing and usage data, replacing the rules-based churn list."
- With the numbers added: "Built an XGBoost churn model on [N] subscriber records; recall on churners rose from [old rules] to [model] on a held-out quarter, and the retention team now sends offers from its scores."
Find the numbers in your evaluation notebook, your experiment tracker or the dashboard the team watches after launch. Not every bullet will have one. An experiment that changed a decision is a result in itself: "Designed a [N]-week test of [feature] on [N] users; it showed no lift in retention, and the team dropped the feature before the full build."
The bullet point generator works right on its page and suggests bullets from your title, level and skills. Then add your metric and your test set yourself.
How do you write an entry-level data scientist resume?
Put education and two or three strong projects near the top, and write each project like a job: the question, the data, the method and how you evaluated it. The intern, graduate student and entry-level samples above all follow this order of evidence: tools named in every bullet, then a measured result where one exists. For the steps before the resume, from core skills to a sample timeline, see our guide on how to become a data scientist.
List relevant coursework such as machine learning, statistics and databases, and your GPA if it's strong. Link each project to its repository or write-up, and include at least one where you collected the data and framed the question yourself, since course datasets usually arrive cleaned. See how to write projects on a resume for layouts.
Coming from an analyst job? Compare the data analyst resume examples with the entry-level sample above: the analyst bullets report what was found, and the data science bullets report what was predicted or tested. If your work is closer to trading models, see the quantitative researcher resume examples. If you mostly put models into production code, the software engineer resume examples include a machine learning engineer sample.
How should you format a data scientist resume?
Use a reverse-chronological layout: a header with city, state, email, LinkedIn and GitHub or portfolio links, then summary, experience, projects, education and skills. New graduates can move education and projects above experience. One page fits most early-career resumes. Two pages are reasonable once you have several data science roles and every line is relevant.
Keep standard section headings so recruiters find what they look for, and list papers in a short publications section near the end (see how to list publications on a resume). For layout details, read how to format a resume.
FAQ
What is the difference between a data scientist resume and a data analyst resume?
A data scientist resume leads with models and experiments: what you predicted or tested, how you evaluated it and whether anyone used it. A data analyst resume leads with the questions you answered with SQL, dashboards and reports. Both list SQL and a visualization tool, but a data scientist resume should also name modeling libraries such as scikit-learn or PyTorch and an evaluation metric. Compare the two side by side with the data analyst samples.
Do data scientist jobs require a master's degree?
No, a master's isn't a universal requirement: data scientists typically need at least a bachelor's degree in mathematics, statistics, computer science or a related field, and some employers require or prefer a master's or doctoral degree, according to the Bureau of Labor Statistics. If you have a bachelor's only, lead with work and projects that show the modeling a graduate degree would signal. If you have a graduate degree, put it near the top while you are early in your career.
How do I move from data analyst to data scientist on my resume?
Start with the analyst work that already used modeling or experiments: a forecast you built, a regression that explained churn, an A/B test you designed. Lead each role with those bullets and name the method and the Python or R libraries. Then add one project that predicts something and gets used, such as a scored lead list a sales team worked from. Keep your real analyst title. Your summary can say you're targeting data scientist roles, as the entry-level sample above does.
How do I turn a PhD or academic research into a data scientist resume?
Rewrite each research project as a problem, a method and a result someone outside your field can use, as the PhD sample above does with power-grid anomaly models. "Built a Bayesian hierarchical model of [N] patient records in Stan; the results changed [which protocol or decision]" says more than a paper title. Cut the CV down to the projects that match the posting, move papers to a short section near the end, and name the languages and libraries you wrote code in.
Should I list Kaggle competitions on a data scientist resume?
Yes, when you placed well or the problem matches the job, and write them as projects. A medal or a top-percent finish is a concrete result: "Top [X]% of [N] teams in a tabular fraud detection competition; LightGBM with target encoding." Competitions hand you a defined dataset and a fixed metric, so pair a Kaggle entry with at least one project where you collected the data and framed the question yourself.
How do I show generative AI or LLM work on a data scientist resume?
Show it the way you'd show any model: the task, the approach, how you evaluated it and what it changed. Name the approach (prompting with retrieval, fine-tuning, an agent with tools), the models and frameworks, and the evaluation. A pattern: "Built a retrieval-augmented assistant over [N] support articles; answer accuracy on a [N]-question test set rose from [A]% to [B]%, and [share] of tickets were resolved without an agent." Without the test set and the scoring method, a reader can't check the result.
How do I describe confidential models on a data scientist resume?
Describe the type of model, the decision it supported and the size of the change, and leave out client names, proprietary features and any figure your employer treats as confidential. Relative changes and ranges usually work: "Built a credit-risk model for a [regional lender] that cut manual reviews by about [X]%." If you are unsure, check your employment agreement or ask your manager what can be shared.